Author: cplatt_owner

  • Alex Hormozi: Best Landing Page Practice

    Alex Hormozi: Best Landing Page Practice

    He distrusted experts for the same reason a farmer distrusts weather prophets: they are often right in general and wrong in time to ruin a crop.

    That is the first thing to notice in Alex Hormozi’s landing-page strategy. He ignores much of what is called best practice online, not because he is reckless, but because he is practical. He does not begin with fashion. He begins with constraint. A business wants more customers. It increases ad spend. Cost rises. Lead quality falls. The machine groans. Most owners respond by trying to force more fuel through a leaky engine.

    Hormozi asks the better question: what is stopping this from scaling?

    That question has the plain severity of a good military question or a good frontier question. Not What are we excited about? Not What are others doing? What is stopping us? Usually the answer is not traffic. It is conversion. The page does not persuade enough of the people already arriving. The business pays more and more to fetch visitors, then quietly loses them at the door.

    This is not glamorous work. It is corrective work. But most profitable work is.

    The heart of the strategy is efficiency. If acquiring attention is an auction, then the winner is not merely the one with the deepest purse. It is the one who can earn the most from each customer and therefore spend more to acquire him without dying from the effort. That sounds obvious once stated, which is usually the mark of a sound business idea. The hard part is behaving as though it were true.

    Most companies do not. They obsess over traffic because traffic is visible and exciting. Conversion is humbler. It requires patience, measurement, and the willingness to admit that the page you were proud of may be underperforming. A man will often spend twenty thousand dollars driving people to a page he has barely examined. There are homesteaders who inspect their fences more carefully than some executives inspect their sales process.

    Hormozi’s emphasis falls first and heavily on the section above the fold. That phrase sounds technical, but the principle is ancient. The beginning matters most. The first look, the first line, the first impression. On a landing page, this is the part every visitor sees before scrolling. If sixty percent never go farther, then this section carries the burden of the entire case. To neglect it is like writing a sermon whose first paragraph sends half the congregation home.

    So he puts most tests there: headline and image. That is sensible. A headline is not decoration. It is the sharp edge of the argument. It tells the visitor, in the fewest possible words, why he should care and whether this page is for him. Most pages fail here because they prefer vagueness. They say the company name. They repeat a category. They announce themselves in language so bloodless that no actual human want appears anywhere in it.

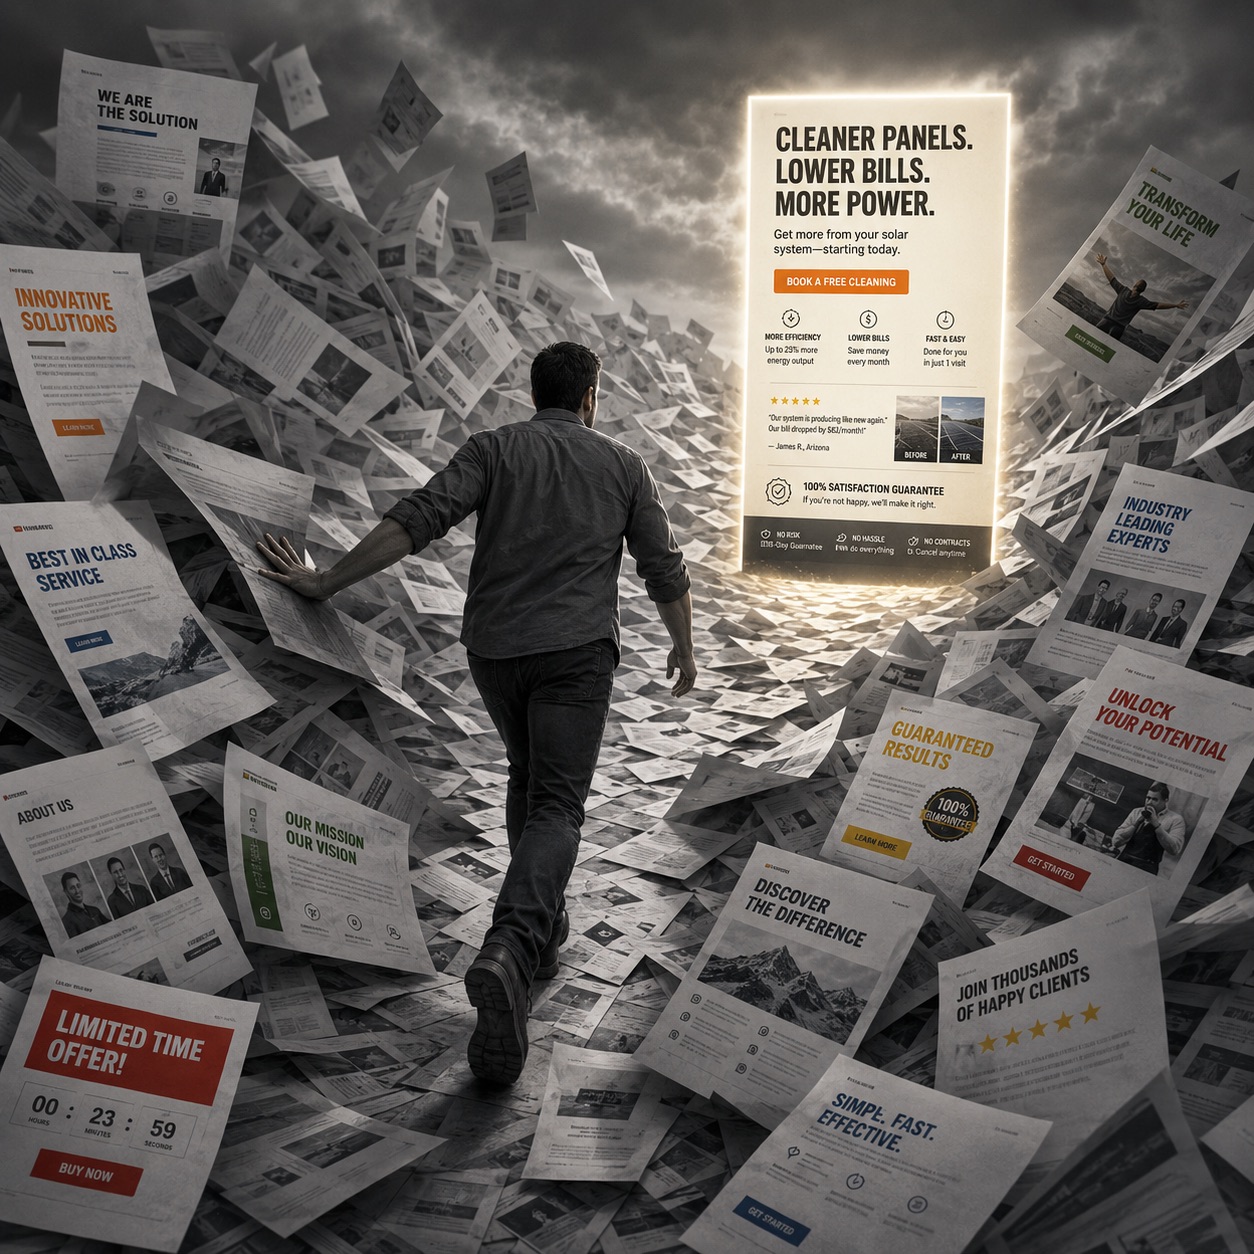
    Hormozi instead reaches for what he calls the dream outcome. This is simply the result the customer wants badly enough to pay for. Not the service itself, but the end it serves. People do not want exterior cleaning in the abstract. They want cleaner solar panels so the system works better, the bill drops, and the purchase feels justified. They do not want mediation training as an academic object. They want a six-figure practice. They do not want dental work merely because teeth exist. They want a straighter, brighter smile and the social ease that comes with it.

    This is one of the old truths of persuasion: people buy the future they can imagine. A page should show that future quickly.

    The hero image should do the same work in visual form. If the headline promises a luxury closet, show the closet. If it promises transformed skin, show the skin. If it promises weight loss, show the body changed. The image should not merely fill space or satisfy a designer’s appetite for atmosphere. It should corroborate the claim. Words promise; images make the promise feel nearer.

    Then comes the second great labor: increasing the perceived likelihood of success. Here Hormozi leans on proof, and rightly. Promise is cheap because anyone can make one. Proof is dear because it has to survive reality. Testimonials, reviews, results, screenshots, before-and-after photos, videos of actual outcomes—these all tell the visitor that the offer has already worked in the world outside the page.

    He is especially shrewd about how proof should appear. Plain text reviews still matter, but they no longer carry the whole load. The internet has taught people suspicion. A wall of anonymous praise means little when anyone can fabricate it. Visual proof is stronger because it feels less abstract. A claimed result may be doubted; a demonstrated result demands more effort to dismiss. A person saying he lost twenty pounds is one thing. Images of the change are another. Video is stronger still because it carries the untidy texture of reality.

    Hormozi also understands accumulation. One testimony may intrigue. Many can overwhelm resistance. This stacking of proof is persuasive for the same reason a courtroom prefers multiple witnesses to a single one. The case begins to feel settled. Not certain—nothing involving human beings is certain—but settled enough to act.

    He also reduces risk. Guarantees, warranties, free trials, return policies, clear promises under the call-to-action button—these all lower the emotional toll of saying yes. Every purchase carries fear: fear of being cheated, fear of wasting money, fear of looking foolish. Risk reversal addresses that fear directly. This is not manipulation. It is courtesy, if the promise is honest. A seller who believes in his offer should be willing to shoulder part of the uncertainty.

    The next two parts of his framework are time delay and effort. They are related because people want good outcomes soon and with as little strain as possible. Again, this is not decadent; it is human. If one path promises a result in thirty days and another in twelve months, the shorter path has an advantage. If one requires heroic discipline and the other offers support, simplicity, and a few plain steps, the easier path wins attention.

    So the page should say not only what result is possible, but how soon it begins and how manageable the process is. The subheadline often bears this weight. It clarifies the claim and softens the toil attached to it. A service that includes personal support, coaching, tutoring, installation, or done-for-you elements should say so. People are not merely buying an outcome. They are buying relief from confusion and burden.

    That is why the “how it works” section matters when done well. Not as a mechanical list, but as reassurance. Three steps feel possible. Six steps feel like homework. This is one of those tiny numerical truths that sensible copywriters learn by experience. A long list can be accurate and still be harmful. People measure difficulty before they measure merit.

    Hormozi’s broader instruction about headlines is also sound. Most visitors scan. They read the page the way a scout reads a tree line: quickly, looking for signs. If the headlines alone do not tell the story, much of the story will never be heard. So generic labels like “How It Works,” “Why Choose Us,” or “What Customers Say” waste valuable territory. A headline should carry meaning, not merely indicate where meaning might be found beneath it.

    That principle is more radical than it sounds. It means every major section should be able to argue its own case even if the body copy is skipped. If your uniqueness matters, state it in the headline. If the process is simple, say how simple it is. If customers achieved remarkable outcomes, put those outcomes where the eye cannot miss them.

    None of this works as a one-time exercise. Hormozi’s final insistence is on continual testing. One change per week, one focused experiment, one attempt to beat the control. There is wisdom in the modesty of that cadence. Businesses like to fantasize about dramatic overhauls because drama flatters the ego. But steady testing compounds. A stronger headline, then a better image, then clearer proof, then a sharper offer, then reduced friction around the button—small gains accumulate until the page no longer resembles its former self in performance.

    There is a practical limitation here. Real A/B testing requires traffic. A page with too few visitors cannot produce trustworthy results quickly. In those cases, one works from established principles and larger revisions rather than pretending statistical certainty where none exists. That is another mark of seriousness: not worshiping data beyond what the data can honestly bear.

    What makes this whole strategy persuasive is not novelty. Very little in it is new. Strong beginnings, clear promises, visible proof, reduced risk, simple process, continual testing—these are old disciplines translated into modern pages. The medium changes. Human hesitation does not.

    The internet is crowded with advice that treats persuasion as ornament or trickery. Hormozi’s system, at its best, treats it as engineering. Not cold engineering, because it depends on human desire and fear, but engineering all the same. Find the leak. Patch the leak. Measure the result. Repeat.

    That is why it works. Not because it is magical, and not because it flatters the marketer, but because it respects the transaction. The visitor arrives with doubt, hope, impatience, and limited attention. The page must answer those conditions plainly. If it does, the business scales more easily. If it does not, no amount of additional traffic will save it for long.
  • AI 101: Context. Instructions. Examples

    AI 101: Context. Instructions. Examples

    There is always a moment when a useful tool gets mistaken for a miracle.

    That happens because people are lazy in a very specific way. Not always in effort. Often in thought. They will work hard at the wrong thing if they believe it lets them avoid the harder thing, which is judgment. And when a machine arrives that seems to answer in full sentences, the temptation becomes almost irresistible. Surely this machine can think for me. Surely I can hand over not just the typing, but the choosing. Not just the words, but the idea.

    It cannot. And if you use it as though it can, it will betray you in the most ordinary way possible: by sounding like everybody else.

    AI Hygiene

    What people are now calling AI hygiene is not really about technology. It is about discipline. It is a way of preventing your own sloppiness from contaminating the machine’s output. If you ask one endless chat to diagnose the spot on your arm, explain how to replace a taillight, and then write sales copy, you should not be surprised when the result has the deranged, patchwork quality of a mind that never learned to sort its drawers.

    A new topic deserves a new chat. That is not a clever trick. It is simple housekeeping. Context helps only when it is the right context. Wrong context is not neutral. It is poison.

    By contrast, when a single conversation stays on a single subject, the machine improves with repetition. Not because it has become wise, but because you have finally stopped forcing it to guess. The first answer is often broad, eager, and unreliable. The fourth answer is usually better, because by then you have done what you should have done from the beginning: you have clarified what you wanted.

    That is one of the quiet truths of this whole business. Better output often comes from better correction, not better software.

    There is another truth, less flattering and more necessary. Facts still need checking. Numbers need checking. Studies especially need checking. A machine that writes with confidence can be more dangerous than one that writes badly, because bad writing at least warns you. Smooth writing can sneak a lie past your attention.

    So the rule is plain enough to remember: outsource the typing, not the thinking.

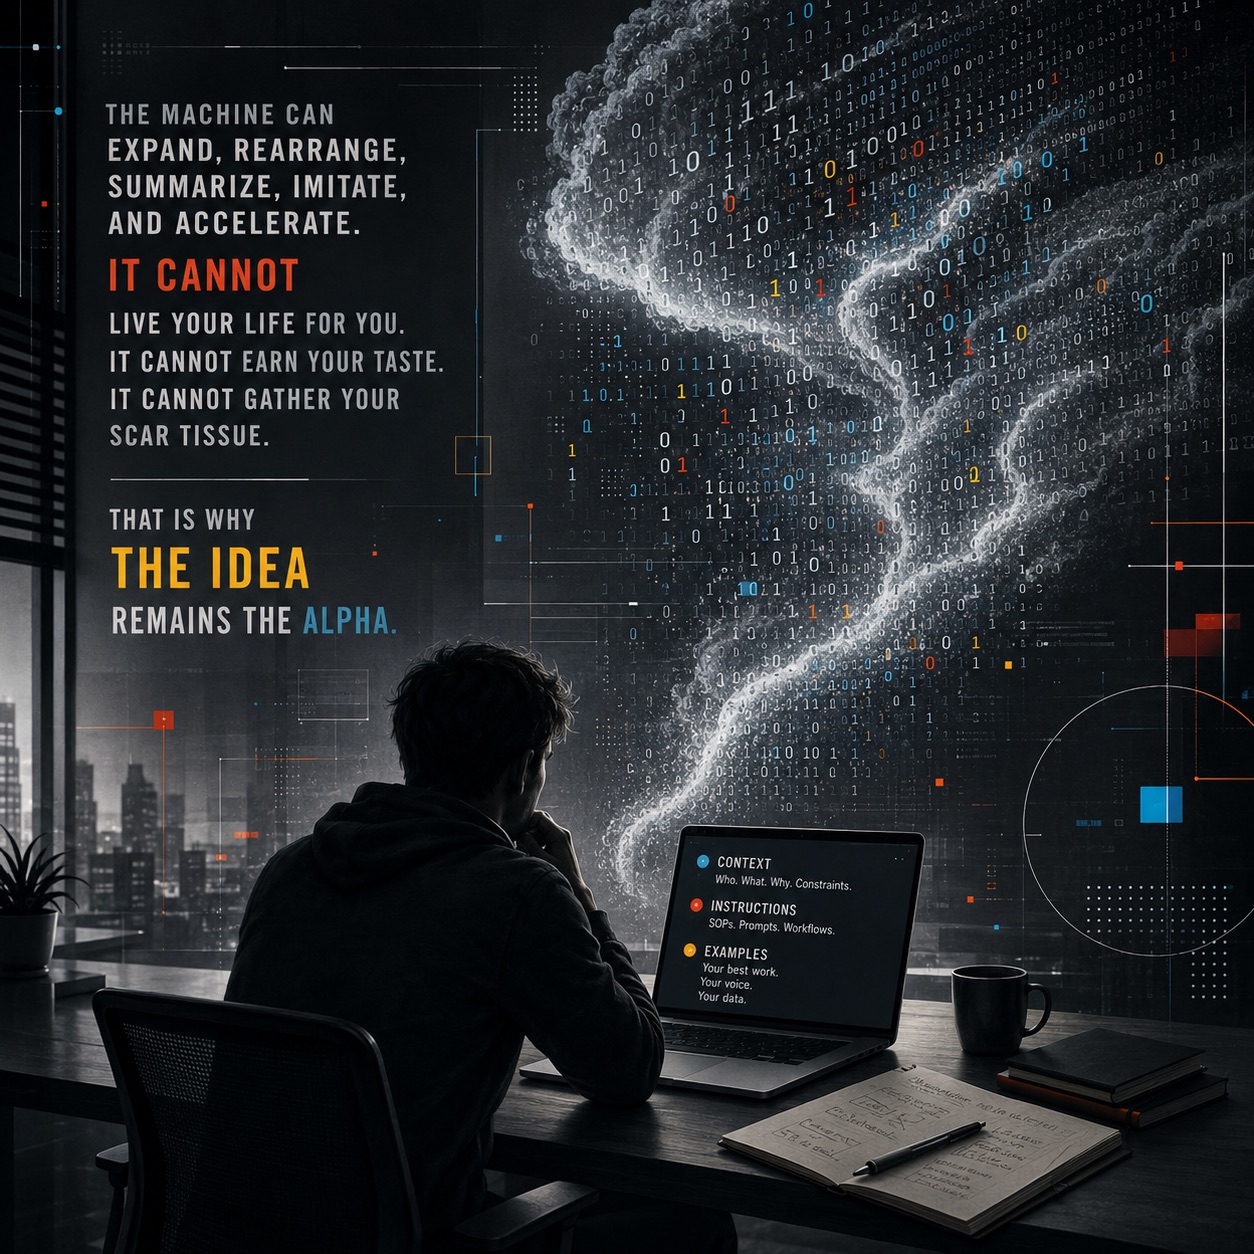
    That sentence matters because too many people imagine that what makes them valuable is the effort of producing words. It is not. Words are cheap. The idea is expensive. The judgment behind the idea is more expensive still. The machine can expand, rearrange, summarize, imitate, and accelerate. It cannot live your life for you. It cannot earn your taste. It cannot gather your scar tissue.

    That is why the idea remains the alpha.

    Context & Instruction

    People who run businesses already understand one version of this, though they often fail to recognize it in the new costume. They know what an SOP is: a standard operating procedure. A repeatable method for getting a repeatable result. Once you see clearly, a prompt is simply an SOP addressed to a machine. Nothing mystical. Nothing futuristic. Just instructions.

    And that is why most prompts fail. They are insultingly short.

    If you would never hand a new employee a single sentence and expect excellent work, why would you do it to a language model? “Write me an email” is not management. It is negligence. The prompt is the procedure. If the procedure is vague, the result will be vague.

    This is where AI moves from novelty to workflow.

    Every business has repeated tasks. Emails. Follow-up. Sales outreach. Customer support. Social posts. Meeting summaries. Proposals. Training materials. Scripts. Internal messages. The list changes by industry, but the pattern does not. If a task repeats, its instructions should be saved. If its instructions should be saved, they can become prompts. And once they become prompts, they can be organized.

    So build a repository.

    That sounds grander than it is. It can be a folder. It can be a master document with tabs. It can be attached to recurring calendar blocks. The container matters less than the habit. What matters is that repeated work stops beginning from zero.

    This is where a great many people lose absurd amounts of time. They do the same thing over and over, badly documented each time, and call the repetition experience. Experience only becomes leverage when it is captured.

    If you do the same task every week, then doing it well once and preserving the method is one of the sanest investments you can make. That is true for a human team. It is true for AI. The machine doesn’t need inspiration. It needs instructions.

    And yet even good instructions are not enough.

    Examples

    Because there is another reason AI writing so often smells wrong the moment you read it. It is not because AI has one voice. It is because its default voice is the average of too many voices. It sounds like the internet because, in a sense, it is the internet speaking with all its rough edges filed off. It has fluency without personality. Competence without blood.

    So if you want it to sound like you, you must give it you.

    Not your wish to sound distinctive. Your actual prior work.

    This is where the idea of assets becomes more important than most people realize. Every business that has been operating for any meaningful length of time has already created a treasury of examples. Old emails. Social posts. Sales calls. Customer support transcripts. Webinars. Product FAQs. Video transcripts. Sales pages. Lead nurture sequences. Objection handling. Pitch decks. Internal onboarding documents. Good ads. Bad ads. Frequently repeated explanations. The useful phrase said a hundred times to a hundred customers. All of it is material.

    All of it is data.

    And the people with the greatest advantage are not the people with the newest tools. They are the people with the richest archive of their own work.

    If you have years of newsletters, the machine can study your rhythm. If you have transcripts of your best sales calls, it can identify what you ask, where the buyer leans in, which words lower resistance, which sequence produces trust. If you have your best short posts, it can discover your compression, your punch, your way of turning a thought so it lands.

    Then, instead of saying, “Sound good,” you can say, “Sound like this.”

    That is a much more powerful command.

    It also explains why beginners who hope to flood the world with machine-made content rarely produce anything worth reading. They have no reservoir. No body of work. No tested cadences. No hard-won language. They have not done enough of the real thing to train the imitation.

    A machine cannot fake depth on behalf of someone who has none.

    That is why the structure of a sensible AI system inside a business becomes almost embarrassingly simple. First, gather business context: what the company is, who it serves, what it sells, how it speaks, what constraints matter. Second, save the SOP-prompts for recurring tasks. Third, collect the data sources that show what good work already looks like.

    Context. Instructions. Examples.

    Those three things, working together, are what turn AI from a toy into leverage.

    And leverage is the right word. Automation is often the wrong one.

    People love the fantasy of automation because it flatters them. Set it once, walk away forever, watch value rain from the ceiling. That does happen occasionally, in narrow and carefully engineered systems. But most of the time what you get is not full replacement. What you get is amplification.

    A task that took ninety minutes may now take twenty. A weekly writing burden may shrink to a half-day each month. A rough idea can become a polished first draft before your energy is gone. A sales manager can review more calls because the machine can help categorize objections and extract recurring failures. A founder can generate variants faster, compare options faster, test angles faster.

    That is not trivial. It is enormous. But it is not magic. The machine has not become your replacement. It has become your multiplier.

    And this matters because multipliers reward people unevenly. They favor those who already have something worth multiplying.

    A weak thinker with AI can produce more weakness. A strong thinker with AI can produce more strength. The old law remains in force: the rich get richer. Here, richness means clarity, taste, experience, discipline, and a body of prior work. The machine magnifies those, too.

    That is why the final error is the most common and the most costly. People think AI generates value because it generates volume. But volume is not value. Most businesses do not need more words. They need better words arranged around a better idea.

    The founder who knows exactly what happened on the sales floor, exactly what the customer fears, exactly where the friction lies, exactly which promise can be made and kept—that person has the scarce resource. The machine can help package it. It cannot originate the lived understanding behind it.

    Conclusion

    So the practical lesson is not difficult, only demanding.

    Start a new chat when the topic changes. Stay in the same chat long enough to refine. Check facts. Keep your own judgment. Save prompts for repeated work. Gather the evidence of your best prior work. Feed the machine context, instructions, and examples. Use it to accelerate execution, not replace discernment.

    And above all, remember that the precious thing is not the paragraph.

    It is the mind behind the paragraph.

    If that mind is lazy, no machine will save it.

    If that mind is disciplined, experienced, and clear, then at last the machine becomes what it should have been all along: not an author, not an oracle, but a tireless clerk taking dictation from somebody who still knows what matters.

  • Win with AI by building adaptive workflows that multiply judgment, learning speed, creativity, and human responsibility.

    Win with AI by building adaptive workflows that multiply judgment, learning speed, creativity, and human responsibility.

    The most honest thing in that whole conversation is also the least glamorous: technology usually does not destroy a business all at once. It simply makes some businesses better run than others. Then, over time, the better-run ones become harder to compete with.

    That is why so many people can point to some stubborn, half-primitive operator who still makes money with methods that should have died twenty years ago. The welder who lives by fax. The seller who closes a deal through direct messages and a blurry bank screenshot. The local company with no software stack, no dashboard, no grand theory of optimization, and yet somehow it keeps going. People see that and draw the wrong lesson. They think it proves technology is optional.

    It only proves that markets are merciful for longer than they ought to be.

    A business can survive while being inefficient. It can even thrive if the owner is unusually competent, unusually hardworking, or sheltered in a market where customers are slow to compare alternatives. But if two people are equally good, and one of them uses tools that multiply speed, reach, coordination, and consistency, then the contest is not close. The more competitive the field, the less room there is for romance about doing things the old way.

    That is the real business effect of AI and robotics, whether we are talking about Open Claw, Clawbot, or any of the parade of systems now appearing with miraculous promises and embarrassing demos. They will not produce an instant divide between the living and the dead. They will produce a sorting. Owners who are willing to become more technologically enabled will gain efficiency first, then margin, then flexibility, then pricing power. Owners who are not willing will often continue to make money for a while, which is precisely what makes complacency so seductive.

    Fear is the excuse. Comfort is the reason.

    Most resistance to new tools does not come from principled caution. Caution has a useful place. You should hesitate before giving autonomous systems access to customer records, payments, inventory, communications, or anything else that can damage trust in a single afternoon. There are genuine risks. There are systems deployed badly, supervised badly, and understood hardly at all. But sensible people isolate risk. They use guardrails. They test in narrow conditions. They do not shrug and call paralysis wisdom.

    The owner who says, “What if it breaks something?” is often really saying, “I do not want to do the hard work of learning enough to use it safely.”

    That pattern appears everywhere. Human beings have a lovely gift for disguising laziness as prudence.

    Yet the strange thing about AI is that even where it helps, it also cheapens. It can increase the productivity of one person while reducing the value of the labor that used to justify a team. It can make one excellent operator almost absurdly powerful. It can also turn a whole category of mediocre output into dust. That is why so much of the internet already feels thin, repetitive, and false. Captions that all sound as if they were generated from the same nervous template. Testimonials with the same clipped rhythm. Messages that keep insisting a thing is not this, not that, not the other, but rather some inflated abstraction. The reader senses the vacancy even before he can name it.

    The ugliness of AI is not only that it can think for people. It is that people are so eager to stop thinking.

    Once a person lets the machine make the decision, write the note, frame the argument, soften the tone, and produce the summary, that person often no longer knows why the result is what it is. He has outsourced not just labor, but understanding. This is efficient in the same way that sawing off your legs is efficient if your goal is to stop buying shoes.

    So we get two movements at once. On one side, businesses that use AI to strip out operational drag and scale faster than before. On the other side, a growing hunger for signs of actual human presence.

    That second part matters more than many technologists realize.

    When imitation becomes abundant, reality becomes precious. When synthetic friendliness, synthetic beauty, synthetic writing, synthetic advice, and synthetic intimacy flood the field, the thing they imitate does not disappear. It becomes more desirable. People may accept a substitute for a while. They often do. But a substitute does not satisfy in the same way. Social media is not friendship. Pornography is not love. Endless generated content is not insight. They are imitations that scratch an itch and leave the skin raw.

    That is why the future is unlikely to belong to the mushy middle. Businesses will be pushed toward one of two poles. At one extreme are the highly automated, highly leveraged, operationally disciplined firms that use AI with ruthlessness and skill. At the other are businesses that offer unmistakable reality: community, craft, presence, trust, taste, physical experience, direct contact with a person who is plainly there and plainly alive.

    The mediocre middle gets punished because it offers neither efficiency nor soul.

    A digital, people-heavy, operations-heavy business may benefit enormously from AI because coordination is expensive and machines are getting surprisingly good at reducing coordination costs. Marketing agencies are an obvious case. Businesses always want customers. Demand rarely disappears. The problem is that service businesses get strangled by headcount, process complexity, and the petty friction of managing many moving parts. If AI allows such a company to deliver a wanted result with fewer people, tighter systems, and better margins, then the value of that company rises very quickly.

    But that same logic creates a threat. Once the operational burden drops, more competitors can enter. So the winners will not merely be those who use AI. The winners will be those who use it while preserving judgment, taste, and a clear promise to the customer.

    That word, judgment, may be the most important one.

    A machine can execute a workflow. It cannot bear responsibility in the human sense. It cannot take a risk and own the consequence. In business, risk still belongs to persons. The one who signs the lease, guarantees the debt, puts his name on the result, stands in front of the customer, and remains standing when things go wrong—that person still matters. Perhaps more than before. If AI and robotics automate more and more labor, then risk-bearing becomes one of the last irreducibly human forms of value.

    This is one reason business ownership will remain so potent, even if many roles inside businesses change beyond recognition. The owner decides, commits, and suffers. That cannot be simulated away. At least not by any machine any sane customer should trust.

    There is another shift coming, and it is less dramatic to describe, but probably more useful. Owners will need to stop thinking in terms of roles and start thinking in terms of workflows. The old language of titles and seats on an org chart becomes less helpful when half the work inside a role can be automated, a quarter can be outsourced, and the remaining quarter requires a human being with discernment. The real question is no longer “Do I need a marketing coordinator?” but “What inputs and outputs in this process create value, and which parts of that process must still be done by a human?”

    That is a harder question. It is also a better one.

    The owners who answer it well will discover that AI is not magic. It is leverage. And leverage rewards clarity. If you do not understand your business, automation will not save you. It will simply accelerate your confusion.

    This is why the sentimental arguments about staying “authentic” by refusing tools are mostly childish. A hammer does not make a carpenter false. Software does not make a business dishonest. The corruption comes when the owner begins to surrender thought, responsibility, and standards. Use the machine to handle drudgery, pattern recognition, scheduling, formatting, triage, drafting, and repetition. Fine. But if you use it to avoid learning your trade, understanding your customer, or making hard choices, then the machine has not strengthened your business. It has hollowed it out.

    Business owners should take a plain lesson from all this.

    • Adopt technology where it creates real advantage.
    • Limit risk with real guardrails.
    • Do not confuse comfort with prudence.
    • Do not confuse output with thought.
    • And do not imagine that customers cannot tell the difference between something made by a person who cares and something shoveled out by a system that does not.

    The next few years will reward two kinds of seriousness: the seriousness to automate what should be automated, and the seriousness to protect what should remain human.

    Anyone who can do both will be dangerous.

  • Transtack Hacked!

    Transtack Hacked!

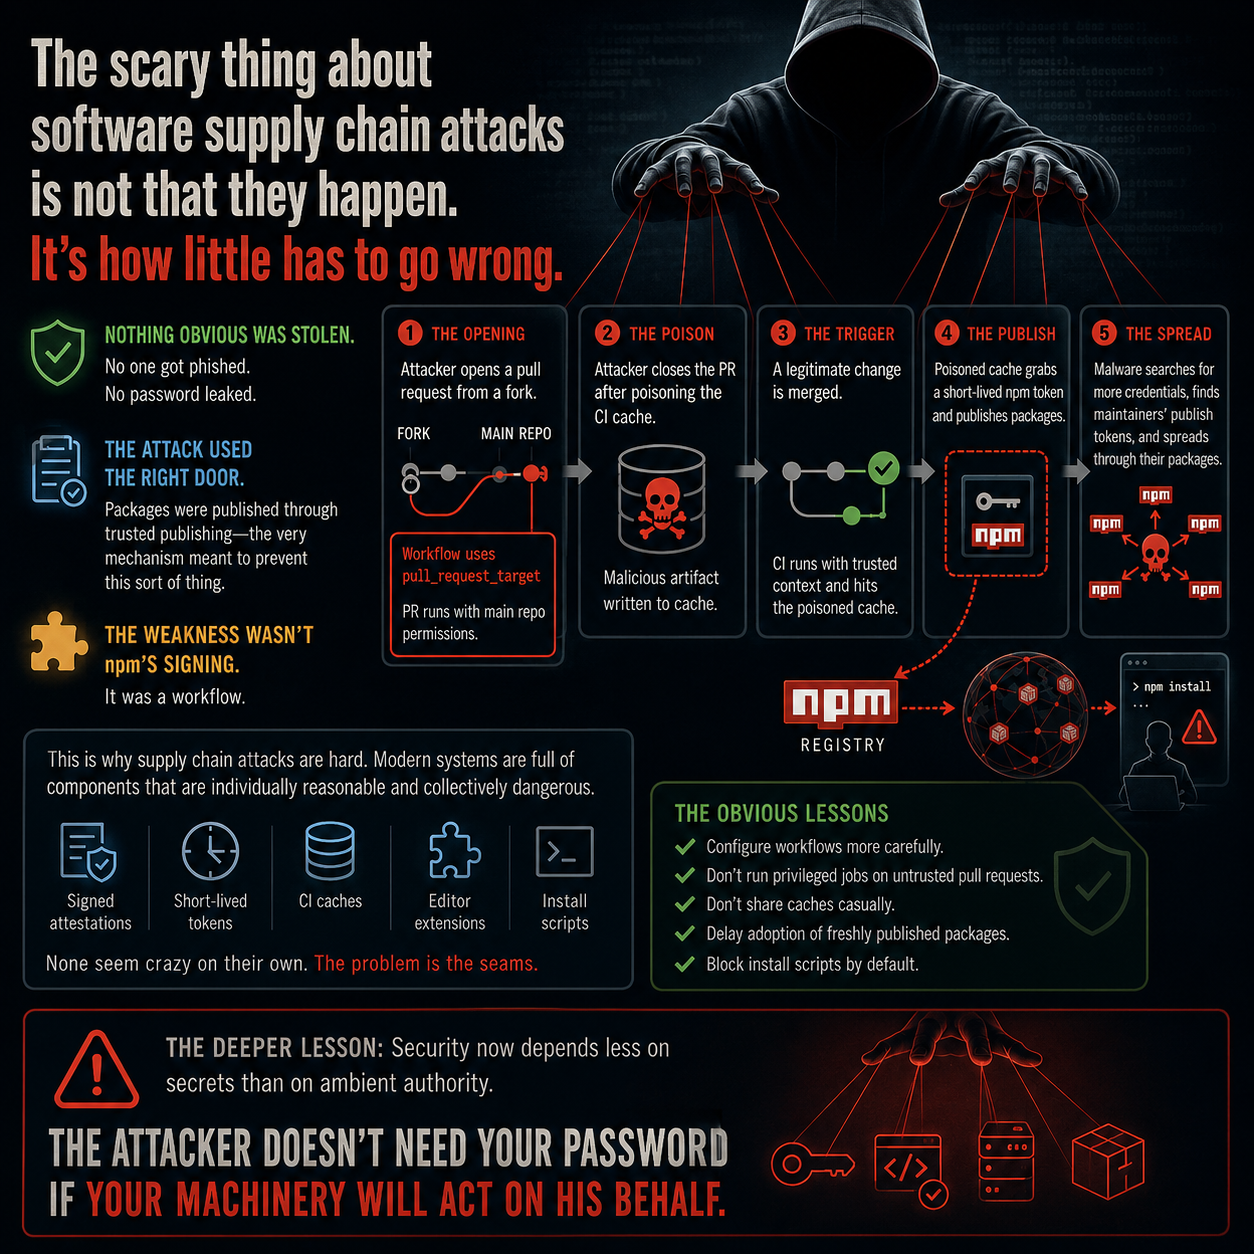
    The scary thing about software supply chain attacks is not that they happen. It’s how little has to go wrong.

    In this case, nothing obvious was stolen. No one got phished. No password leaked. The packages were published through the very mechanism meant to prevent this sort of thing: trusted publishing. That is what makes the attack interesting.

    The weakness was not npm’s signing. It was a workflow.

    A project used pull_request_target, which is one of those features that sounds convenient when you’re setting it up and ominous when you understand it. A pull request from a fork could run with the main repository’s permissions. The attacker created one, closed it, and used that brief opening to poison the CI cache.

    That was enough.

    Later, when a real change was merged, the poisoned cache woke up, grabbed a short-lived npm token, and published compromised packages. Then the malware did what worms do: looked for more credentials, found maintainers’ publish tokens, and spread outward through their packages too.

    This is why supply chain attacks are hard. Modern systems are full of components that are individually reasonable and collectively dangerous. Signed attestations, short-lived tokens, CI caches, editor extensions, install scripts—none seem crazy on their own. The problem is the seams.

    The obvious lesson is to configure workflows more carefully. Don’t run privileged jobs on untrusted pull requests. Don’t share caches casually. Delay adoption of freshly published packages. Block install scripts by default.

    But the deeper lesson is that security now depends less on secrets than on ambient authority. The attacker doesn’t need your password if your machinery will act on his behalf.

  • I Rebuilt a Popular App… But Simpler: A Team Chat App Build Breakdown

    I Rebuilt a Popular App… But Simpler: A Team Chat App Build Breakdown

    Reverse engineering apps is one of the fastest ways to level up as a developer. Not because you should copy a product feature-for-feature, but because rebuilding a familiar experience forces you to think like both a product designer and a systems engineer.

    For this breakdown, I rebuilt the core of a popular team chat app—think channels, threaded conversations, and workspace membership—but in a much smaller, cleaner form. No enterprise billing. No sprawling permissions matrix. No endless settings screens. Just the part that teaches the most about product scoping and app architecture.

    That constraint matters. The biggest collaboration apps in this category support millions of users and sit at the center of daily work for companies around the world. At that scale, the hard parts are reliability, search, permissions, integrations, and real-time delivery. In a smaller build, you can isolate the architectural ideas without getting buried in edge cases.

    If you’ve ever wanted a practical clone app tutorial that goes beyond “here’s the folder structure,” this is the version I wish I had. I’ll walk through what I built, what I intentionally left out, and how I made the frontend/backend split simple enough to ship while still teaching real system design basics.

    Quick Preview of the Build

    Here’s the path I followed:

    1. Pick the smallest version of the product that still feels real
    2. Define the domain model before writing UI code
    3. Design APIs around user actions, not database tables
    4. Keep the frontend fast by separating server state from local UI state
    5. Build real-time updates as an enhancement, not a dependency
    6. Make clear tradeoffs around search, scale, and permissions
    7. Leave out the expensive features on purpose

    The result was a simpler team chat app with:

    • Workspaces
    • Channels
    • Members
    • Messages
    • Threads
    • Read tracking
    • Basic search over recent messages

    That’s enough to feel useful, and enough to surface real architecture decisions.


    1. Start by Shrinking the Product Scope

    What I did

    Instead of trying to rebuild an entire collaboration platform, I defined a strict “version 1”:

    • A user can join a workspace
    • A workspace has channels
    • A channel contains messages
    • A message can have thread replies
    • Users can read, send, and reply
    • Users can search recent messages inside the workspace

    That was it.

    I explicitly cut:

    • File uploads
    • Reactions
    • Typing indicators
    • Rich text editing
    • Voice/video
    • Bots and integrations
    • Granular admin permissions
    • Cross-workspace search
    • Offline sync
    • Full notification rules

    Why it matters

    This is the part most developers skip when reverse engineering apps. They see the polished product and start coding the visible features, but the real leverage is deciding what not to build.

    A simpler product gives you room to make better architectural decisions. It also helps you understand the shape of the original app. Mature products look complex because they’ve accumulated years of edge cases. Your goal is to identify the minimum interaction loop that makes the app feel authentic.

    For a team chat app, that loop is simple:

    1. Enter workspace
    2. Open channel
    3. Read recent messages
    4. Send message
    5. Reply in thread

    If that loop works well, the app already feels recognizable.

    Common mistake to avoid

    Don’t scope by UI. Scope by user behavior.

    “Sidebar, message list, composer” is not a product definition. “People discuss work in channels and branch side conversations into threads” is.

    Concrete tip

    Before writing code, force yourself to finish this sentence:

    “The app is useful if a user can __.”

    For this build, mine was:

    “The app is useful if a user can join a workspace, follow a channel conversation, and reply without losing context.”

    That sentence guided every architecture decision after that.


    2. Model the Domain Before the Database

    What I did

    I defined the core entities first:

    • User
    • Workspace
    • WorkspaceMember
    • Channel
    • ChannelMember (optional depending on privacy model)
    • Message
    • ThreadReply
    • ReadState

    A simplified relational model looked like this:

    users
    workspaces
    workspace_members
    channels
    messages
    read_states

    Key relationships:

    • A workspace has many members
    • A workspace has many channels
    • A channel has many messages
    • A message may belong to a parent message for threading
    • A read state tracks the last seen message per user per channel

    I used a single messages table for both top-level messages and replies:

    • id
    • workspace_id
    • channel_id
    • author_id
    • parent_message_id nullable
    • body
    • created_at
    • edited_at
    • deleted_at

    Top-level channel messages had parent_message_id = null. Thread replies referenced the parent.

    Why it matters

    This is one of the most important app architecture decisions in the whole build.

    Using one table for both messages and replies keeps the write path simple. You don’t need two separate content systems. You can still query:

    • channel timeline = messages where parent_message_id is null
    • thread replies = messages where parent_message_id = :messageId

    That gives you a clean model without over-engineering.

    Common mistake to avoid

    Don’t create a table for every visible UI component.

    A “thread panel” is not a database entity. It’s just a filtered view over messages.

    Example schema decision

    I also avoided storing derived counts too early. For example, instead of immediately adding reply_count to every message, I computed it on read for the first version.

    Why? Because cached counters make writes more complex:

    • send reply
    • update thread count
    • maybe publish event
    • maybe invalidate cache

    That’s worth doing later, not on day one.


    3. Design the API Around Workflows, Not CRUD

    What I did

    I avoided a generic “CRUD everything” backend and designed endpoints around the core flows.

    Example API surface:

    GET    /workspaces/:workspaceId
    GET    /workspaces/:workspaceId/channels
    GET    /channels/:channelId/messages?cursor=...
    POST   /channels/:channelId/messages
    GET    /messages/:messageId/thread
    POST   /messages/:messageId/replies
    POST   /channels/:channelId/read
    GET    /workspaces/:workspaceId/search?q=...

    A message creation payload stayed intentionally small:

    {
      "body": "Ship the migration after lunch?"
    }

    A thread reply looked like:

    {
      "body": "Yes, as long as the backfill completes first."
    }

    Why it matters

    When you’re building a simpler version of a popular app, API design should mirror what the user is trying to do.

    Users do not think in terms of:

    • create message record
    • update parent entity
    • refetch aggregate

    They think in terms of:

    • post into channel
    • open thread
    • reply to thread
    • mark channel as read

    That makes the backend easier to understand and the frontend easier to wire.

    Common mistake to avoid

    Don’t expose your database structure directly as your API contract.

    If your frontend needs three requests and client-side joins just to open a channel, the API is too low-level.

    Concrete tip

    Return UI-ready shapes for the highest-traffic screens.

    For example, the channel timeline response included:

    • message author summary
    • message body
    • created timestamp
    • reply count
    • whether current user has read past this point

    That slightly denormalized response reduced frontend complexity a lot.


    4. Draw a Hard Line Between Server State and UI State

    What I did

    I split frontend state into two buckets:

    Server state

    • workspace
    • channels
    • messages
    • thread data
    • search results
    • read markers

    Local UI state

    • selected channel
    • open thread panel
    • draft message text
    • search modal visibility
    • optimistic sending state

    This sounds obvious, but it’s the difference between a maintainable app and a fragile one.

    Why it matters

    A chat interface changes constantly. If you mix network data and UI behavior into one giant store, you’ll spend more time debugging state synchronization than building features.

    The boundary I used was:

    • If it originates from the backend or needs revalidation, treat it as server state
    • If it only affects the current screen interaction, keep it local

    That made the app much easier to reason about.

    Common mistake to avoid

    Don’t put draft composer text in the same cache layer as fetched messages.

    One is ephemeral user input. The other is shared backend data. They have different lifecycles.

    Example frontend boundary

    The channel screen had three independent pieces:

    1. Message timeline query
    2. Thread query for selected parent message
    3. Local composer state

    That separation made it easy to:

    • refetch messages without clearing drafts
    • switch threads without losing the channel timeline
    • optimistically render a sent message while the network request finished

    5. Add Real-Time Carefully Instead of Building Around It

    What I did

    I built the app to work without real-time first.

    The initial version used:

    • paginated fetch for channel messages
    • periodic refresh or manual revalidation
    • optimistic updates after sending

    Then I layered in WebSocket or event-stream updates for:

    • new messages in the active channel
    • new thread replies for the open thread
    • read marker updates

    Why it matters

    This is a major lesson from reverse engineering apps: many “real-time” products are really a mix of durable request/response workflows plus event updates on top.

    If your app only works when the socket is perfect, it will be brittle. If it works fine with plain HTTP and gets better with live updates, it will be resilient.

    That’s the right order.

    Common mistake to avoid

    Don’t make WebSocket events your source of truth.

    The database is the source of truth. Events are delivery hints.

    When the client reconnects, it should be able to recover by refetching the latest channel state.

    Concrete tip

    Use events for invalidation, not reconstruction.

    Instead of sending giant payloads for every change, a simple event like this often works better:

    {
      "type": "channel.message.created",
      "channelId": "ch_123",
      "messageId": "msg_456"
    }

    The client can decide whether to insert optimistically, refetch, or ignore based on context.

    That keeps your event protocol stable.


    6. Make Search and Read Tracking “Good Enough,” Not Perfect

    What I did

    I included two lightweight features that dramatically improved usability:

    • workspace message search over recent indexed content
    • per-channel read tracking using the latest seen message

    Search was intentionally basic:

    • text query
    • workspace-scoped
    • recent messages first
    • no advanced ranking
    • no typo tolerance

    Read tracking was also simple:

    • each user stored a last-read message or timestamp per channel
    • unread count was derived relative to newer messages

    Why it matters

    These are great examples of features that feel “core” to a polished product, but don’t need enterprise-grade complexity in a smaller build.

    You don’t need to build world-class information retrieval to teach system design basics. You just need enough search to demonstrate indexing boundaries and enough read state to support a realistic UX.

    Common mistake to avoid

    Don’t start by calculating exact unread counts across every possible state transition.

    That gets complicated fast once you include:

    • edited messages
    • deleted messages
    • thread-only unread behavior
    • muted channels
    • mentions
    • notification preferences

    For a simpler build, “messages after last seen” is enough.

    Example tradeoff

    I deliberately chose channel-level read state instead of per-message read receipts.

    Why?

    Because channel read tracking solves a real user need with far less write amplification. Per-message receipts create much heavier fan-out and don’t meaningfully improve the learning value of the project.


    7. Decide What Lives on the Backend vs. the Frontend

    What I did

    I kept these concerns on the backend:

    • authorization
    • membership checks
    • message persistence
    • pagination
    • search
    • read state updates
    • event publication

    I kept these on the frontend:

    • active channel routing
    • thread panel behavior
    • draft composition
    • optimistic rendering
    • scroll restoration
    • local filtering and display logic

    Why it matters

    A good build breakdown should make this boundary explicit, because many architecture problems come from putting logic in the wrong place.

    For example:

    • Permission checks belong on the backend, always
    • Whether the thread drawer is open belongs on the frontend, always

    There are gray areas, but most mistakes happen when developers move server rules into client code because it feels faster in the moment.

    Common mistake to avoid

    Don’t trust the client to enforce workspace membership or channel access.

    Even in a demo build, keep authorization on the server. Otherwise your architecture teaches the wrong lesson.

    Concrete tip

    Ask this question for each piece of logic:

    “If I changed clients tomorrow, would this rule still need to exist?”

    If yes, it probably belongs on the backend.


    8. Think About Scale Early, But Only Solve the First Order Problems

    What I did

    I didn’t try to architect for internet-scale traffic. I did, however, make a few decisions that wouldn’t collapse immediately under growth:

    • cursor pagination instead of offset pagination for messages
    • indexes on channel_id, workspace_id, created_at, and parent_message_id
    • append-heavy write model for messages
    • cached channel metadata where useful
    • async event delivery for real-time fan-out

    Why it matters

    The biggest apps in this category handle enormous message volume, global concurrency, and long retention windows. Your simplified build does not need that infrastructure, but it should still reflect the shape of the problem.

    That means solving the first-order issues:

    • timelines should paginate efficiently
    • writes should be simple
    • thread lookups should be indexed
    • reconnect flows should be recoverable

    Common mistake to avoid

    Don’t use offset pagination for an active message stream.

    As messages arrive, offsets drift. Cursor-based pagination is more stable and maps better to time-ordered content.

    Example scaling thought process

    I didn’t build:

    • sharded event infrastructure
    • distributed search clusters
    • per-region message replication
    • advanced cache invalidation

    But I did build with the assumption that:

    • message reads far outnumber message writes in many channels
    • active channels are hot spots
    • thread queries need their own access path
    • search should eventually move out of the primary database if usage grows

    That level of foresight is usually enough for an intermediate project.


    What I Intentionally Left Out

    This was the most important part of the whole exercise.

    I left out features that are expensive, distracting, or mostly orthogonal to the architecture I wanted to study:

    • rich formatting and slash commands
    • file storage pipeline
    • notifications across web/mobile/email
    • organization-wide admin tooling
    • external integrations
    • analytics and audit logs
    • advanced moderation and compliance features

    Why? Because each of those is its own system.

    If I had included them, the project would have become a collection of side quests instead of a focused reverse-engineering exercise.

    A good clone app tutorial is not about copying surface area. It’s about identifying the product’s structural core.


    Mistakes, Edge Cases, and Optimization Tips

    A few things surprised me during the build:

    Threads complicate everything earlier than expected

    As soon as replies can branch away from the main timeline, you have to think carefully about:

    • query patterns
    • unread logic
    • URL structure
    • cache invalidation

    If you want the simplest possible version, build channels first and add threads second.

    Search can dominate architecture if you let it

    The moment users expect great search, you’re no longer “just building chat.” You’re building indexing, ranking, and retrieval systems.

    Keep search intentionally narrow in early versions.

    Real-time UX is often mostly illusion

    A lot of the polish comes from:

    • optimistic inserts
    • smooth scroll behavior
    • clear loading states
    • stable ordering

    Those improvements often matter more than ultra-low-latency infrastructure in a small build.

    Permissions explode fast

    Public channels plus workspace membership are easy. Private channels, guest users, and role-based admin features are not.

    If your goal is to understand core app architecture, stay with a simpler permission model first.


    Final Takeaway

    Rebuilding a popular app in simpler form taught me more than building an “original” side project from scratch.

    Why? Because the constraints were clearer. The user expectations were familiar. And every feature forced a useful question:

    • Is this core, or just polished?
    • Should this be modeled in data, API, or UI?
    • Does this complexity belong now, or later?

    For intermediate developers, that’s the real value of reverse engineering apps. You stop thinking in pages and components, and start thinking in systems, boundaries, and tradeoffs.

    If you want to practice architecture without disappearing into enterprise complexity, this is a great format: pick one recognizable app, reduce it to the smallest honest version, and build that version well.

    If you want to explore the implementation, compare the structure, or adapt the ideas to your own project, Check out the code in the GitHub repos.

  • The One Feature Every SaaS Needs (That Nobody Talks About)

    The One Feature Every SaaS Needs (That Nobody Talks About)

    Most SaaS teams obsess over acquisition, polish their onboarding UX, and debate pricing for months. Then they quietly accept churn as if it were mostly a sales problem.

    It isn’t.

    If I had to pick one underrated feature that meaningfully improves retention, it would not be AI copilots, deeper analytics, or another onboarding checklist. It would be a persistent, contextual “next step” system: a product layer that tells users what to do next, based on where they are, what they’ve already done, and what outcome they’re trying to reach.

    That may sound almost too simple to count as a feature. That is exactly why it’s overlooked.

    In 2026, one of the clearest competitive advantages in SaaS is not having more functionality. It is making forward progress obvious. The products that win are increasingly the ones that reduce user drift between sessions, shorten time-to-value, and make continued usage feel natural instead of effortful.

    That is a retention feature. And most SaaS products still treat it like copywriting.

    Why This Matters Now

    The SaaS market is mature enough that buyers no longer reward feature volume the way they once did. Most categories are crowded. Switching costs are lower than founders want to admit. And the bar for “good enough” software keeps rising.

    That changes the retention equation.

    You do not keep customers simply by shipping more. You keep them by helping them repeatedly realize value. That is the core of effective saas retention strategies, and it has less to do with novelty than with momentum.

    The uncomfortable truth is that many users do not churn because your product is bad. They churn because they lose the thread.

    They log in and ask:

    • What should I do now?
    • What matters most?
    • Did I already set this up?
    • Am I close to getting value?
    • Is there a reason to come back today?

    If your product does not answer those questions immediately, users stall. And stalled users churn.

    The Underrated Feature: A Contextual “Next Step” System

    Let’s define it clearly.

    A contextual next-step system is a persistent part of the product that guides users toward the most valuable action available to them at any moment. It is not just an onboarding checklist. It is not a generic dashboard widget. And it is not a chatbot bolted onto the corner of the screen.

    It is a product-level mechanism that:

    • knows the user’s stage
    • recognizes what they have and have not completed
    • surfaces the next best action
    • explains why it matters
    • updates as the user progresses
    • remains useful after onboarding

    In practical terms, this can look like:

    • a “Next best action” module on the home screen
    • milestone-based prompts tied to setup and usage
    • role-specific guidance for admins, operators, and end users
    • progress indicators connected to outcomes, not just tasks
    • smart empty states that point to the highest-value next move
    • re-entry cues for users returning after days or weeks away

    The important part is not the UI pattern. The important part is the job it does.

    It answers the most retention-critical question in SaaS: How do I keep this user moving?

    Most SaaS Products Are Built for Discovery, Not Continuity

    Here’s the slightly contrarian take: a lot of SaaS teams spend too much time optimizing first-run experiences and not enough time designing for second, fifth, and fifteenth use.

    That is backwards.

    Yes, activation matters. Yes, onboarding UX matters. But retention usually breaks after the welcome tour. It breaks in the gap between initial setup and repeated habit. It breaks when users have to decide what to do without enough context. It breaks when the product assumes motivation will carry the experience.

    It won’t.

    Users are busy. They are interrupted. They log in between meetings. They return after a week and forget what they were doing. They delegate work across teams. They inherit accounts set up by someone else. They open your product with partial knowledge and limited patience.

    A product without a next-step system effectively says, “Here are all the things you can do.”
    A product with one says, “Here is the one thing you should do now to get value faster.”

    That difference sounds small. In retention terms, it is enormous.

    Why This Feature Has an Outsized Impact on Retention

    Good retention is rarely just about satisfaction. It is about continued successful behavior.

    That is why high-level retention metrics should be read carefully. You can improve trial conversion, early engagement, or account stickiness without necessarily fixing long-term churn. But in most SaaS products, the pattern is consistent: users who reach meaningful milestones early and continue progressing are far more likely to stick than users who wander.

    A next-step system improves retention because it supports the mechanics behind churn reduction, not just the appearance of engagement.

    1. It shortens time-to-value

    Users stay when they get to a useful outcome quickly.

    Not when they complete seven setup screens.
    Not when they admire your information architecture.
    When they do something that makes your product matter.

    A contextual next step keeps the product focused on outcome progression. It reduces the cognitive tax of figuring out what to do first, second, and third.

    2. It reduces decision fatigue

    Many SaaS products create unnecessary complexity by exposing too many options too early. That is often framed as power or flexibility. From the user’s perspective, it is friction.

    Every time the user has to choose among ten plausible actions, there is a risk they choose none.

    Retention improves when software narrows the field.

    3. It creates continuity across sessions

    This is the overlooked part.

    Users do not experience your product as one uninterrupted journey. They experience it in fragments. The more your product can preserve context and restore momentum when they return, the more likely they are to keep using it.

    A strong next-step system acts as a memory layer. It tells users where they left off and what will move them forward now.

    4. It aligns product usage with customer outcomes

    Many teams track feature adoption when they should be tracking progress toward value.

    A next-step system forces clarity. If you cannot define the most useful next action for a user, you may not understand your own product’s value path well enough.

    That is a product strategy benefit, not just a UX one.

    The Signals Supporting This Prediction

    Why am I confident this feature will matter even more in 2026?

    Because several larger shifts are converging.

    Software is getting more capable — and harder to navigate

    AI has increased what products can do, but it has also increased complexity. More options do not automatically create better experiences. In many cases, they make products less legible.

    As capability expands, guidance becomes more valuable.

    Buyers are less patient with “figure it out” products

    In crowded categories, users do not give vendors endless time to prove value. They compare tools faster, abandon tools faster, and expect clearer paths to outcomes.

    That makes guided momentum a retention lever, not a nice-to-have.

    Seat expansion depends on clarity

    In multi-user SaaS, retention is not just about one champion. It depends on broader adoption inside an account. That means different users need different prompts, milestones, and next steps.

    Without contextual guidance, usage stays shallow and concentrated. That limits expansion and increases account fragility.

    Metrics are shifting from adoption to realized value

    Sophisticated teams increasingly know that logins and raw activity can be misleading. The stronger signal is whether users are repeatedly reaching meaningful outcomes.

    A next-step system is one of the most direct product mechanisms for increasing the odds of that happening.

    What This Looks Like in Practice

    If you are building for SaaS retention, do not start by asking, “How do we make the app feel more guided?” Start by asking, “What progression actually predicts retention?”

    Then design the feature around that.

    Here’s a practical framework.

    Build Around Milestones, Not Features

    Most next-step modules fail because they recommend product actions instead of customer progress.

    Bad examples:

    • Create a dashboard
    • Invite teammates
    • Explore integrations
    • Try our AI assistant

    Those may be useful, but they are still product-centric.

    Better examples:

    • Connect your first data source so reports stay current
    • Invite the teammate who owns approvals so this workflow can go live
    • Publish your first customer-facing asset
    • Resolve one live issue using the automation you just configured

    The difference is subtle but critical. One list describes software usage. The other describes value creation.

    Retention follows the second one.

    Make It Persistent, Not Seasonal

    Another mistake: teams build guidance for onboarding week and then remove it once the user is “activated.”

    That misses the point.

    The need for direction does not disappear after setup. It changes shape.

    A good next-step system should evolve through stages:

    • new user: complete setup and get first value
    • active user: deepen usage and build habits
    • team account: expand roles and collaborative workflows
    • mature customer: unlock advanced use cases and efficiencies
    • at-risk user: restore momentum after inactivity or stalled progress

    In other words, this is not an onboarding feature. It is a lifecycle feature.

    Design for Re-Entry, Not Just Entry

    This is where many products leave retention on the table.

    When a user returns after a gap, do not make them reconstruct context from scratch. Give them a clear re-entry point:

    • what changed
    • what remains incomplete
    • what action matters now
    • what benefit they get by doing it

    This is one of the highest-leverage areas in onboarding ux, even though it technically happens after onboarding. Re-onboarding is retention design in disguise.

    Keep the Surface Area Small

    The next-step system should reduce noise, not add to it.

    That means:

    • one primary recommendation, not seven
    • simple language, not internal jargon
    • visible rationale, not just commands
    • progress tied to outcomes, not arbitrary completion percentages

    If users see “78% complete” but have no idea why that matters, the system has failed.

    The Obvious Counterargument

    A fair objection is that every SaaS product is different. Some are exploratory. Some are infrequent-use tools. Some are built for experts who hate hand-holding.

    True.

    Not every product should be heavily guided. And not every retention problem can be solved with a next-step layer. If your core value is weak, no amount of progressive prompting will save you. If your implementation process is broken, a dashboard cue will not fix it. If users fundamentally do not need the product often, daily engagement mechanics are irrelevant.

    But that does not weaken the thesis.

    It sharpens it.

    The argument is not that guidance replaces product quality. The argument is that for a large share of SaaS businesses, retention is constrained less by missing features than by missing continuity.

    That is why this feature is so underrated. It does not feel glamorous. It rarely headlines roadmaps. It is easy to dismiss as “just UX.”

    It is not just UX. It is behavior design attached to business outcomes.

    What SaaS Builders Should Do About It

    If you want to improve retention, do this before adding another major feature:

    1. Identify the three behaviors that best predict long-term retention

    Not vanity actions. Real milestones that correlate with repeat value.

    2. Map the moments where users stall

    Look at inactivity gaps, abandoned setup steps, empty states, and low-adoption paths.

    3. Create a single next-step surface in the product

    Start small. One module. One recommendation. One reason it matters.

    4. Personalize by role and lifecycle stage

    Admins, managers, and contributors should not see the same path.

    5. Measure progression, not clicks

    Do users complete meaningful steps faster? Do they return with more continuity? Do stalled accounts recover?

    6. Treat it as a core product system

    Not a one-off growth experiment. Not a temporary onboarding project.

    If you run your SaaS, this is the kind of feature that can quietly outperform far louder roadmap items.

    The Bottom Line

    The most important retention feature in SaaS is often the one nobody brags about: a contextual system that shows users what to do next and why it matters.

    That is the feature.

    Not because it is trendy. Because it addresses a basic truth of product behavior: users stay when progress feels obvious.

    In 2026, the winners in SaaS will not just be the products with the most capability. They will be the products that make momentum easiest to sustain.

    If you want stronger saas retention strategies, better onboarding ux, and real churn reduction, stop thinking only about what your product can do.

    Start thinking harder about how users keep moving.

    Add this to your product today.

  • Java Polymorphism: Overloading, Overriding, Interfaces, and Dynamic Dispatch (Explained)

    Java Polymorphism: Overloading, Overriding, Interfaces, and Dynamic Dispatch (Explained)

    Introduction

    You’ve probably seen this moment in Java:

    You call a method on a variable that looks like one type, but at runtime it behaves like a different one. Maybe you expected one output… and got another.

    Or you wrote two methods with the same name (overloading), then later added a subclass and overrode one of them—only to realize Java chose a different method than you thought.

    These bugs aren’t random. They’re the result of how Java handles polymorphism, specifically overloading, overriding, interfaces, and dynamic dispatch. Let’s make these concepts feel predictable instead of mysterious.

    Main Concepts

    Polymorphism in plain English

    Polymorphism means: the same method call can result in different behavior depending on the situation.

    In Java, that “situation” is usually either:

    • Compile-time type (what the variable is declared as)
    • Runtime type (what object you actually have)

    Java uses both in different ways depending on whether you’re dealing with overloading or overriding.


    Overloading: compile-time choice

    Overloading happens when multiple methods have the same name in the same class (or subclass) but different parameter lists.

    Java decides which overloaded method to call based on the compile-time types of the arguments.

    That means overloading is mostly determined before the program runs.

    Example:

    class Calculator {
        int add(int a, int b) {
            return a + b;
        }
    
        double add(double a, double b) {
            return a + b;
        }
    }

    If you call add(1, 2) you’ll get the int version, because both arguments are compile-time int.

    But if you do:

    Calculator c = new Calculator();
    System.out.println(c.add(1, 2.0));

    Java will select the best match based on the compile-time argument types (here: int + double triggers numeric conversions and selects the double overload).

    Key point: overloading does not depend on runtime object type. It depends on the method call signature Java sees at compile time.


    Overriding: runtime choice

    Overriding happens when a subclass provides a new implementation of a method declared in a superclass.

    Unlike overloading, overriding is resolved using the runtime type of the object.

    That’s where polymorphism really kicks in.

    Example:

    class Animal {
        void speak() {
            System.out.println("Animal sound");
        }
    }
    
    class Dog extends Animal {
        @Override
        void speak() {
            System.out.println("Woof");
        }
    }

    Now compare:

    Animal a = new Dog();   // compile-time: Animal, runtime: Dog
    a.speak();              // prints "Woof"

    Even though the variable a is declared as Animal, the JVM calls Dog.speak() because the actual object is a Dog.

    Key point: overriding is dynamic dispatch.


    Dynamic dispatch: the mechanism

    Dynamic dispatch is the runtime process that selects the correct overridden method implementation.

    When you call a.speak(), Java doesn’t just “look up” speak() in the Animal class and stop there. Instead, it checks the actual runtime class of a and invokes the method that matches that class’s override.

    This is what makes polymorphism useful: you can write code against a general type (Animal) and still get specific behavior (Dog, Cat, etc.).


    Interfaces: polymorphism without inheritance

    You can achieve polymorphism using interfaces too—often preferred in real code because it avoids deep inheritance trees.

    An interface defines a contract:

    interface Payment {
        void pay(int amount);
    }

    Different classes implement it:

    class CardPayment implements Payment {
        @Override
        public void pay(int amount) {
            System.out.println("Paid " + amount + " using a card");
        }
    }
    
    class CashPayment implements Payment {
        @Override
        public void pay(int amount) {
            System.out.println("Paid " + amount + " using cash");
        }
    }

    Now write code against the interface:

    void checkout(Payment payment) {
        payment.pay(50);
    }

    Call it like this:

    checkout(new CardPayment()); // Paid 50 using a card
    checkout(new CashPayment()); // Paid 50 using cash

    Same method call (pay(50)), different behavior at runtime. That’s polymorphism via interfaces + dynamic dispatch.


    Putting it together: compile-time vs runtime

    A good mental model:

    • Overloading: decided at compile time using argument types.
    • Overriding: decided at runtime using the object’s actual type.

    Mix those up and you’ll get surprising results.

    Example

    Let’s build a small scenario that includes overloading, overriding, and interfaces in one place.

    Step 1: Define an interface with an overriding target

    interface Shape {
        int area();                 // overridden implementations
        String describe();         // overridden implementations
    }

    Step 2: Create two implementations

    class Rectangle implements Shape {
        private final int w;
        private final int h;
    
        Rectangle(int w, int h) {
            this.w = w;
            this.h = h;
        }
    
        @Override
        public int area() {
            return w * h;
        }
    
        @Override
        public String describe() {
            return "Rectangle";
        }
    }
    
    class Square extends Rectangle {
        private final int side;
    
        Square(int side) {
            super(side, side);
            this.side = side;
        }
    
        @Override
        public int area() {
            return side * side;
        }
    
        @Override
        public String describe() {
            return "Square";
        }
    }

    Step 3: Add overloading in a separate utility method

    class Printer {
        // Overloaded: compile-time selection
        void print(Shape s) {
            System.out.println("Shape: " + s.describe() + ", area=" + s.area());
        }
    
        void print(Rectangle r) {
            System.out.println("Rectangle-ish: " + r.describe() + ", area=" + r.area());
        }
    }

    Step 4: Observe what happens when you call overloaded methods

    public class Demo {
        public static void main(String[] args) {
            Printer printer = new Printer();
    
            Shape shape = new Square(4);     // compile-time Shape, runtime Square
            Rectangle rect = new Square(4);  // compile-time Rectangle, runtime Square
    
            printer.print(shape);
            printer.print(rect);
        }
    }

    What to expect:

    • printer.print(shape):

      • Overload choice uses compile-time type: Shape
      • It calls print(Shape s)
      • Inside, s.describe() and s.area() use dynamic dispatch:
      • shape is actually a Square, so you get "Square" and 16
    • printer.print(rect):

      • Overload choice uses compile-time type: Rectangle
      • It calls print(Rectangle r)
      • Again, overridden methods (describe, area) are selected at runtime from Square

    This example highlights the “two-stage” behavior: overloading picks the method, then overriding chooses the behavior inside.

    Practical Use

    1) Write flexible code with interfaces

    When you define something like Payment, Notification, or Storage, you can build the rest of your system around that interface. That keeps your code open for extension:

    • Add PayPalPayment later without rewriting the checkout flow.

    2) Use @Override aggressively

    Junior devs often forget @Override, and then accidentally create a new method instead of overriding (wrong signature, different parameters, etc.). With @Override, the compiler helps you catch the mistake early.

    @Override
    public int area() { ... }

    3) Prefer overriding for behavior, overloading for convenience

    Overloading is great for APIs that accept different input types, like:

    • read(String path)
    • read(Path path)
    • read(File file)

    Overriding is for polymorphic behavior—like different shapes, animals, renderers, strategies, etc.

    4) Expect dynamic dispatch in polymorphic code

    If you have:

    List<Shape> shapes = List.of(new Square(2), new Rectangle(2, 3));
    for (Shape s : shapes) {
        System.out.println(s.describe() + ": " + s.area());
    }

    You should expect each element to call its own overridden implementation.

    Common Mistakes

    Mistake 1: Assuming overloading uses runtime types

    Consider:

    class A {}
    class B extends A {}
    
    class Test {
        void m(A a) { System.out.println("A"); }
        void m(B b) { System.out.println("B"); }
    }

    If you do:

    Test t = new Test();
    A x = new B();
    t.m(x);

    You might want "B", but Java prints "A" because overload selection uses compile-time type (A), not runtime type (B).

    Mistake 2: Confusing “is-a” with “has-a”

    Polymorphism feels like inheritance, but interfaces help you express capability:

    • Square implements Shape (capability)
    • not Square is-a Rectangle as the only design tool

    Inheritance is not always the right first choice.

    Mistake 3: Forgetting that fields don’t use dynamic dispatch

    This one surprises people. If you override a field (you can’t truly override fields in Java like methods; you can hide them), polymorphism doesn’t behave the same way.

    Methods dispatch dynamically; fields are selected differently. If you need polymorphic state, store it in methods or use separate objects.

    Mistake 4: Overriding without matching the signature

    If you write:

    class Cat extends Animal {
        void speak(int volume) { ... } // different signature
    }

    You didn’t override speak(). You added a new method. Calls to speak() still use Animal.speak() unless the signature matches.

    Conclusion

    Java polymorphism is powerful, but it has two distinct “selection rules”:

    • Overloading is chosen at compile time based on the declared argument types.
    • Overriding uses dynamic dispatch at runtime based on the actual object type.
    • Interfaces make polymorphism flexible and composable, often reducing reliance on deep inheritance.
    • Dynamic dispatch is what makes Animal a = new Dog(); a.speak(); print “Woof”.

    Practical takeaways

    • Use overriding for behavior differences between subclasses/implementations.
    • Use overloading for convenience when multiple input shapes can map to the same concept.
    • Program to an interface when you want extensibility.
    • Always annotate overrides with @Override.
    • When something “feels wrong,” ask: Did Java choose the method based on compile-time or runtime types?

    Once you internalize that split, polymorphism stops being a source of surprises—and becomes a tool you can rely on.

  • I Built My Own Version of Git

    I Built My Own Version of Git

    For years, I used Git the way most developers do—confident enough to get by, but not confident enough to explain why it works.

    I could commit, push, and rebase my way through projects, but Git always felt a little… magical.

    So I decided to remove the magic.

    I built a simplified version of Git in Python.


    The Goal

    I didn’t want to rebuild Git completely. That would take months (or years). Instead, I focused on the core idea:

    Can I build a system that tracks file history using hashes?

    That led to a small CLI tool with just a handful of commands:

    tig init
    tig add file.txt
    tig commit -m "message"
    tig log
    tig checkout <hash>
    

    Simple on the surface—but surprisingly deep once you start building it.


    The Big Idea: Content-Addressable Storage

    The first breakthrough came when I stopped thinking in terms of files and started thinking in terms of content.

    In a normal filesystem, you store something like:

    file.txt
    

    But in Git (and in my version), you store:

    <hash> → file contents
    

    Here’s the core function that made everything possible:

    def hash_object(data: bytes) -> str:
        return hashlib.sha1(data).hexdigest()
    

    That’s it.

    Every file, every commit, every snapshot—everything is identified by its hash.

    This leads to a powerful property:

    If two files have the same content, they have the same hash.

    Which means:

    • No duplication
    • Built-in integrity checking
    • Deterministic state

    Storing Files as “Blobs”

    When I implemented add, I realized something interesting: Git doesn’t care about filenames at first—it cares about content.

    Here’s the simplified version of what happens:

    def add(file_path):
        with open(file_path, "rb") as f:
            content = f.read()
    
        data = b"blob\n" + content
        blob_hash = write_object(data)
    

    A couple subtle but important details here:

    • I prefix the content with "blob\n"
    • The hash is calculated on the entire structure

    That means the same content stored as a different type (like a commit) will produce a different hash.

    This is how Git avoids collisions between object types.


    The Hidden Layer: The Index (Staging Area)

    One of the most misunderstood parts of Git is the staging area.

    When I built my own version, it finally clicked.

    I stored it as a simple JSON file:

    {
      "file.txt": "a1b2c3..."
    }
    

    Every time you run:

    tig add file.txt
    

    You’re not committing—you’re updating this index.

    That separation is crucial.

    It means:

    • You can stage multiple files
    • You control exactly what goes into a commit
    • Commits become predictable snapshots

    Commits Are Just Objects

    Before this project, I thought commits were something special.

    They’re not.

    They’re just structured data.

    Here’s what my commit object looks like:

    {
      "tree": "abc123",
      "parent": "def456",
      "message": "first commit",
      "timestamp": 1710000000
    }
    

    And here’s the key insight:

    A commit doesn’t store files—it points to a tree, which points to blobs.

    That indirection is what makes Git so powerful.


    Rebuilding History

    The log command ended up being one of my favorites to implement.

    It’s just a loop:

    while current:
        commit = read_object(current)
        print(commit["message"])
        current = commit["parent"]
    

    That’s it.

    Git history is just a linked list of commits.

    No database. No complex indexing.

    Just pointers.


    The Moment It Clicked

    The most satisfying moment came when I implemented checkout.

    I took a commit hash, walked to its tree, loaded each blob, and rewrote the files on disk.

    And suddenly:

    I could travel through time.

    Not metaphorically—literally.

    I could restore my project to any previous state using nothing but hashes.

    That’s when Git stopped feeling like a tool and started feeling like a system.


    What I Didn’t Build (and Why It Matters)

    My version is intentionally simple. It doesn’t include:

    • Branching
    • Merging
    • Diffs
    • Remote repositories

    And that’s important.

    Because it highlights something:

    The core of Git is surprisingly small.

    Everything else—branches, merges, rebases—is built on top of:

    • content-addressable storage
    • immutable objects
    • commit chains

    What I Learned

    Building this changed how I think about version control.

    1. Git is a database, not just a tool

    It’s storing objects, not files.

    2. Hashing is the foundation

    Everything depends on deterministic hashing.

    3. Simplicity scales

    The core model is simple—but incredibly powerful.


    Final Thoughts

    I didn’t build a production-ready replacement for Git.

    But I built something more valuable:

    Understanding.

    And now when I run:

    git commit
    

    I know exactly what’s happening under the hood.


    If You Want to Try This

    I highly recommend building your own version.

    Start small:

    • Store files as hashes
    • Build a commit object
    • Walk the history

    You don’t need thousands of lines of code.

    You just need the right mental model.


    What’s Next

    If I keep going, I want to explore:

    • Branching (just pointers!)
    • Merging (this gets complicated fast)
    • A better CLI experience

    But even if I stopped here, this project was worth it.

    Because now Git isn’t magic anymore.

    It’s just really elegant engineering.

    To check out the code you can see the repository on my github https://github.com/plattnotpratt/tig-repo-clone

  • The New Developer Renaissance: How AI Is Changing Software Development (For the Better)

    The New Developer Renaissance: How AI Is Changing Software Development (For the Better)

    Not long ago, writing software meant hours of staring at stack traces, typing boilerplate code, and Googling obscure errors at 2 a.m.

    Today?

    You might simply ask an AI:

    “Build me an API that does this… and write the tests.”

    Welcome to the age of AI-assisted development—a time when developers are no longer just coders, but architects of ideas.

    And the change isn’t theoretical anymore. It’s happening right now.

    AI Has Officially Entered the Developer Toolkit

    AI in development has moved from novelty to industry standard.

    Recent research shows that around 90% of developers now use AI tools in their workflow and many spend roughly two hours a day collaborating with AI systems. 

    Even more striking:

    • 92% of developers use AI tools somewhere in their workflow
    • 51% use them daily
    • ~41% of code in real workflows is AI-generated  

    But here’s the important part:

    AI is not replacing developers.

    It’s supercharging them.

    From Autocomplete to Autonomous Engineers

    The first generation of coding AI was simple:

    • autocomplete suggestions
    • documentation help
    • syntax corrections

    Now we’re entering the era of agentic development.

    Modern AI coding tools can:

    • read an entire codebase
    • plan implementation steps
    • modify multiple files
    • run commands
    • open pull requests automatically  

    In other words:

    AI has evolved from “pair programmer” to junior teammate.

    Some tools are even pushing beyond that.

    The Rise of AI Coding Agents

    Today’s development environment includes an entire ecosystem of AI tools:

    Examples include:

    • GitHub Copilot
    • Cursor IDE
    • Claude Code
    • Amazon Q Developer
    • Google Gemini Code Assist
    • Replit Agents

    These tools can:

    • generate full applications
    • refactor legacy systems
    • create tests automatically
    • debug issues
    • manage CI/CD pipelines  

    Companies are rapidly adopting them because the gains are real.

    At Nvidia, for example, AI coding tools helped engineers produce three times more code than before, while maintaining stable bug rates. 

    That’s not just productivity.

    That’s a transformation of how software is built.

    Developers Are Becoming Idea Multipliers

    Historically, building software required:

    1. Idea
    2. Design
    3. Weeks of coding

    Now?

    AI collapses the timeline.

    A single developer can:

    • prototype a product in hours
    • test an idea the same day
    • iterate instantly

    This has created a new culture called “vibe coding.”

    Instead of manually writing every line, developers guide the AI:

    “Make it faster.”

    “Add OAuth.”

    “Rewrite this in Rust.”

    And the system responds.

    AI Is Also Democratizing Development

    Perhaps the most exciting change isn’t speed.

    It’s access.

    AI tools allow:

    • designers to prototype apps
    • founders to build MVPs
    • students to learn programming faster
    • non-developers to automate workflows

    Some AI platforms can even generate entire web apps from prompts.

    This means the next generation of software might not come from giant teams.

    It might come from one curious person and a clever AI assistant.

    The New Developer Workflow

    A modern developer’s day increasingly looks like this:

    1. Describe the feature in plain English
    2. Let AI generate a draft implementation
    3. Review and refine
    4. Ask AI to write tests
    5. Run automated debugging
    6. Ship

    AI handles the repetitive tasks.

    Developers handle the thinking.

    That shift is profound.

    But It’s Not Magic (Yet)

    Let’s be honest: AI is powerful, but imperfect.

    Studies show developers still review most AI-generated code because accuracy and reliability vary. 

    Only about 30% of AI-generated suggestions are accepted directly in some workflows. 

    Which is actually a good thing.

    It means the real future isn’t:

    AI vs developers

    It’s:

    AI + developers

    The Future: AI-Native Development

    The next wave is already forming.

    New tools are introducing agent-first development environments, where multiple AI agents collaborate on coding tasks simultaneously. 

    Imagine:

    • one AI writing backend logic
    • another designing the UI
    • a third testing performance
    • a fourth managing deployment

    While the developer acts as creative director.

    Software development is becoming less about typing syntax and more about orchestrating intelligence.

    The Real Transformation

    The biggest shift isn’t technical.

    It’s philosophical.

    For decades, programming was about writing instructions for machines.

    Now it’s about collaborating with them.

    AI removes the friction between imagination and execution.

    That means:

    • more experimentation
    • faster innovation
    • smaller teams building bigger products

    And possibly a golden age for builders.

    Final Thought

    The world often frames AI as a threat to developers.

    But history shows something different.

    Every major tool—from compilers to frameworks—once raised the same fear.

    Instead of replacing developers, those tools made them more powerful.

    AI is simply the next step.

    Not the end of programming.

    But the beginning of a new creative era in software development.

    If you want, I can also help you turn this into:

    • a more opinionated viral blog version,
    • a Medium-style storytelling article, or
    • a technical deep-dive version developers will love. 🚀
  • 10 Software Ideas to Kickstart Your Programming Journey

    10 Software Ideas to Kickstart Your Programming Journey

    Embarking on the journey of software development is both exciting and daunting. Whether you’re a beginner looking to dip your toes into coding or an experienced programmer seeking new challenges, there’s always room for innovative software ideas. In this blog, we’ll explore ten project ideas that cater to programmers at different skill levels, from novices to seasoned developers.

    Project Ideas for Beginners:

    1. To-Do List Application: Create a simple to-do list app that allows users to add, edit, and delete tasks. This project helps beginners understand basic CRUD (Create, Read, Update, Delete) operations.
    2. Calculator: Build a basic calculator application that performs arithmetic operations like addition, subtraction, multiplication, and division. This project introduces fundamental concepts of user input and output.
    3. Weather App: Develop a weather application that fetches weather data from an API and displays it to the user. This project teaches beginners how to work with APIs and handle JSON data.

    Project Ideas for Intermediate Programmers:

    1. Blog/CMS (Content Management System): Create a simple blogging platform where users can write, edit, and publish articles. This project involves database management, user authentication, and CRUD operations.
    2. E-commerce Website: Build an online store with features like product listings, shopping carts, and checkout processes. This project delves into more complex web development concepts like session management and payment gateways.
    3. Chat Application: Develop a real-time chat application that allows users to communicate with each other. This project introduces concepts like WebSockets and event-driven programming.

    Project Ideas for Advanced Programmers:

    1. Machine Learning Model Deployment: Build a web application that utilizes a machine learning model for tasks like image recognition or sentiment analysis. This project involves integrating machine learning algorithms with web frameworks like Flask or Django.
    2. Blockchain-Based Application: Create a decentralized application (DApp) using blockchain technology. This project explores concepts like smart contracts, distributed ledgers, and cryptographic hashing.
    3. Operating System Kernel: Develop a basic operating system kernel with functionalities like process management, memory allocation, and file systems. This project requires a deep understanding of computer architecture and systems programming.
    4. Game Development: Create a multiplayer game using a game engine like Unity or Unreal Engine. This project encompasses various aspects of game development, including graphics rendering, physics simulation, and network programming.

    Embarking on software projects is an excellent way to hone your programming skills and explore new technologies. Whether you’re a beginner, intermediate, or advanced programmer, there’s a project idea suited to your level of expertise. Start small, gradually increase the complexity of your projects, and most importantly, enjoy the learning journey!